Why digital conversations still feel a bit “off”
You’ve probably seen a slick avatar demo where everything looks fine, yet the exchange still feels slightly unnatural. The mismatch usually isn’t one obvious flaw; it’s a handful of small ones that add up. A reply lands a beat too late, or too fast. The voice sounds clear but doesn’t “breathe” with the sentence. The face moves, but the emphasis isn’t where a human would put it. Even accurate lip-sync can feel wrong if timing, stress, and pauses don’t match the meaning.
Real conversations also carry low-level signals that most tools simplify: quick acknowledgments, interruptions that resolve smoothly, and subtle changes in energy when a topic shifts. Once you add practical constraints like network latency, microphone noise, and model safety filters that sometimes refuse or hedge, the interaction can start to feel cautious or mechanical. The goal isn’t perfection; it’s reducing these stacked frictions enough that the audience stops noticing the interface.
What makes an AI avatar feel like a real person
Picture a live customer call: the person on the other end doesn’t just deliver correct words. They anticipate when to speak, they signal they’re listening, and they adjust their tone when you sound confused or rushed. An AI avatar feels “real” when it reproduces those interactive behaviors reliably, not when it has perfect skin texture or a high-resolution face.
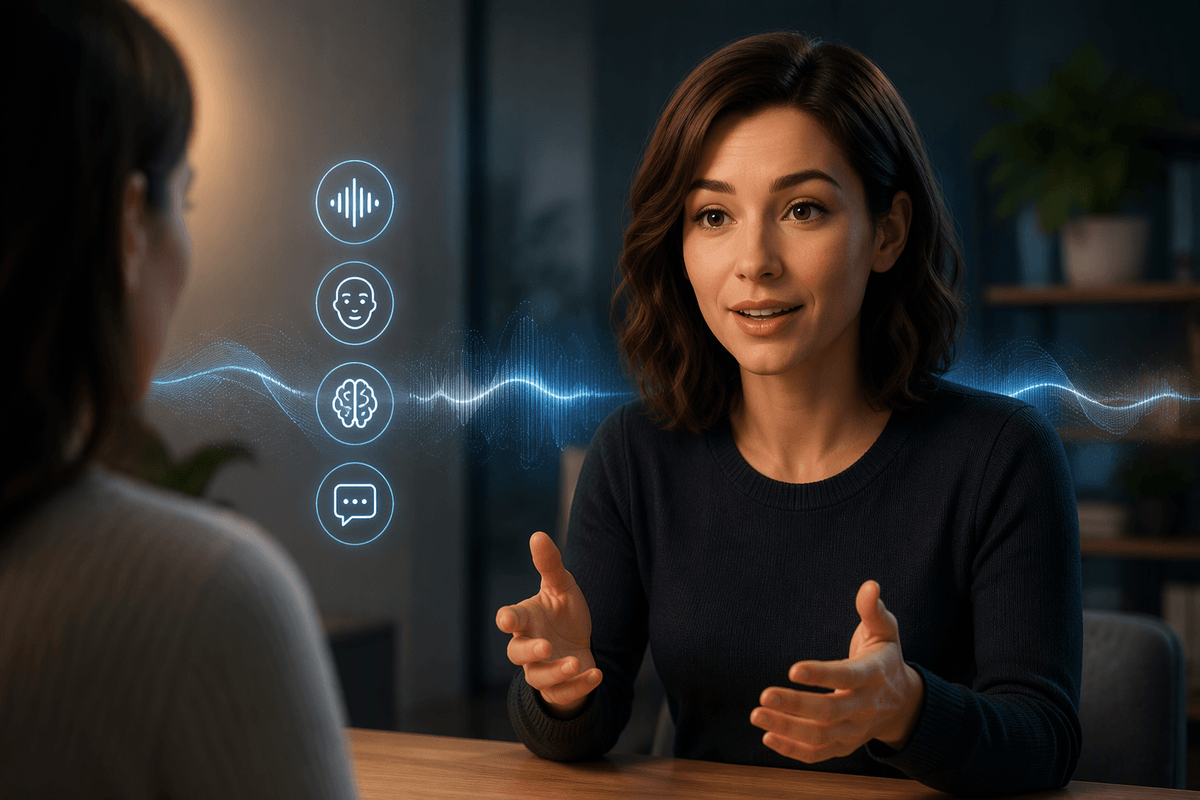
The core ingredients are alignment and consistency across channels: the voice’s prosody matches the meaning, the mouth shapes match the phonemes, the eyes and brows support emphasis, and the response timing fits the moment. Micro-behaviors matter—short backchannels (“mm-hm”), quick self-corrections, and natural pauses before a sensitive answer. Memory helps when it stays coherent (using the same names, preferences, and goals), and it hurts when it confidently misremembers.
In practice, realism is bounded by constraints: even a few hundred milliseconds of extra latency can flatten turn-taking, and safety layers can introduce awkward refusals. Those limits shape which use cases will feel effortless versus staged.
Speech, timing, and turn‑taking do most of the work
Think about the last video call where you kept talking over someone. Nothing was “wrong” with their face or audio quality; the timing was. In avatar conversations, speech rhythm and turn-taking carry most of the realism signal because they’re what humans use to coordinate in real time. A voice that speeds up slightly on key points, drops volume on asides, and uses short fillers (“yeah,” “right,” a quick inhale) will often feel more human than a perfectly neutral voice with flawless lip-sync.
When latency pushes responses past the moment where a nod or “mm-hm” should have happened, the exchange starts to feel like a chatbot with a face. Good systems handle overlap gracefully: they pause when you interrupt, resume without repeating too much, and ask a clarifying question when they detect uncertainty. The practical constraint is cost and complexity—low-latency streaming, interruption handling, and prosody control are harder to ship reliably than a good-looking render.
Face and body cues: subtle beats perfect detail
Watch a real listener on a video call: they don’t perform constant “acting,” but they do small, well-timed things that keep the exchange grounded. A tiny nod when you finish a clause, a brief eyebrow lift on surprise, eyes that settle on you when you’re making a point, and a micro-smile that appears and fades quickly. These cues work because they’re synchronized with meaning and timing, not because they’re visually perfect.
Avatar demos often overinvest in face detail and underdeliver on coordination. If the head nod loops every two seconds, if gaze snaps between targets, or if the shoulders stay rigid while the voice sounds engaged, people notice the pattern. The body is a consistency check: posture shifts, breathing motion, and small hand movements should support emphasis, then get out of the way. There’s a practical cost here—adding full-body tracking, stable gaze control, and emotion-driven animation increases compute and can add latency. Many deployments do better by keeping movement restrained and prioritizing a few reliable signals over constant motion.
Avoiding the uncanny valley in real deployments
You can usually predict uncanny reactions by watching where a system overcommits. A highly realistic face paired with slightly wrong timing, gaze, or emotional emphasis reads as “trying to be human” and missing, which is more unsettling than a simpler style. Many teams get better results by choosing a deliberately stylized avatar, limiting expressiveness to a few reliable cues, and avoiding constant idle motion that becomes a loop people learn to spot. Realism also drops when the avatar’s confidence doesn’t match its actual certainty; a warm, direct delivery of a wrong answer feels deceptive fast.
Deployment adds pressures demos avoid: variable bandwidth, noisy mics, and safety filters that can force sudden topic changes or refusals. Plan for graceful failure modes—clear disclosure that it’s AI, a visible handoff to a human, and conservative claims when identity or authority matters. Anti-misuse controls (consent for voice likeness, watermarking or provenance when possible) add friction and cost, but they reduce the reputational risk that comes from a “too real” avatar used in the wrong context.
Conversation realism depends on memory and intent
The quality of an AI avatar becomes clearer over several exchanges. When every message is treated as a new prompt, the responses may remain fluent but lack a sense of continuity. Natural conversation depends on keeping track of the shared context: the user’s goal, decisions already made, current concerns, and topics that do not need to be revisited. Remembering a preferred name, using the same definition of “launch date,” or avoiding repeated questions about an order helps the interaction feel attentive and consistent.
Memory needs clear boundaries and safeguards. Personalization loses value when an avatar recalls details incorrectly or retains sensitive information that should not persist. Intent matters just as much. An avatar helping diagnose a problem should ask different questions from one teaching a concept or qualifying a sales lead, and its explanations should reflect that purpose. Maintaining context, protecting private information, and keeping the avatar’s intent consistent across channels all require engineering, review, and ongoing investment.
Putting it together: a practical realism checklist
You can pressure-test realism with a short checklist: does it respond within the conversational window (including quick “mm-hm” or a nod), and can it handle interruptions without derailing? Does prosody match meaning—stress, pauses, softening on sensitive points—or is it flat with a talking mouth? Do gaze and small head movements track the speaker without looping patterns? Can it carry the task across turns (names, goals, constraints) without inventing memories? Finally, does the deployment plan cover the unglamorous parts: bandwidth variation, clear AI disclosure, consent for likeness, a human handoff, and a safe failure mode when it’s unsure?