Why “train on-device” is suddenly appealing
A familiar pattern is playing out across mobile, IoT, healthcare, and finance: teams have plenty of user interactions, sensor readings, or clinical notes, but moving that data into a central warehouse is slow, expensive, and increasingly hard to justify. Regulations and contracts add friction, and even when collection is “allowed,” the optics and internal risk reviews can stall projects for months.
Training on-device becomes appealing because it flips the default. Instead of shipping raw data to the model, the model goes to the data and learns locally. That can reduce data-transfer exposure and unlock signals that never leave a phone, a hospital network, or a branch system. You now pay in coordination—battery, connectivity, uneven hardware, and the ongoing cost of operating a distributed training pipeline.
What actually moves: model updates, not raw data
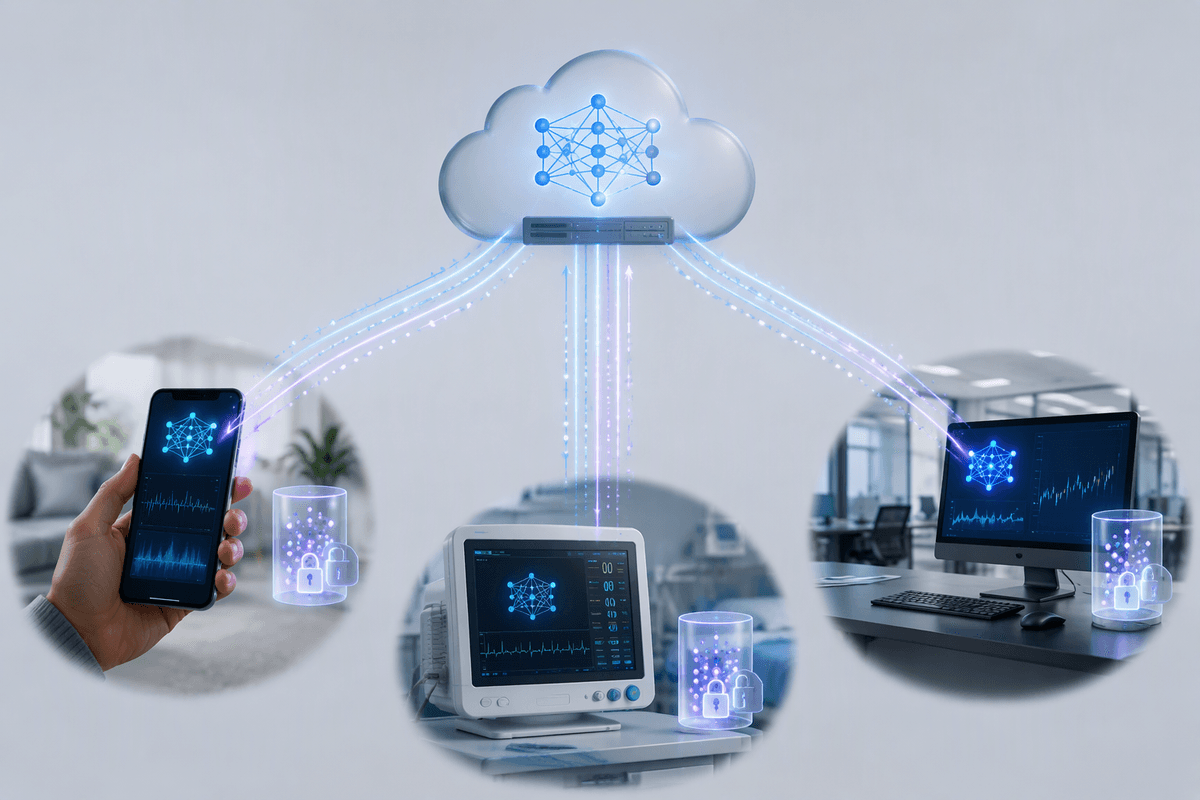
Picture a keyboard app, a bedside monitor, or a risk-scoring tool inside a bank network. Each environment keeps its raw records where they already live, runs a short training job on a local slice of data, and produces a small set of changes to the model—often gradients or updated weights. Those updates are what get sent out, typically to a coordinating server that averages or otherwise aggregates them into a new “global” model. The improved model is then shipped back to participants for the next round.
This distinction matters for both privacy and engineering. “No raw data leaves” can simplify compliance conversations, but the updates are still derived from sensitive data, so they’re not automatically safe to share. It also shifts your bottleneck: instead of moving giant datasets once, you move many smaller updates repeatedly, and the cost shows up as network traffic, slower iteration, and the need to handle stragglers and dropouts without stalling training.
Your first decision: cross-device or cross-silo setup
You usually face an early fork: are you coordinating millions of personal devices, or a smaller number of organizations and servers? Cross-device federated learning looks like phones, wearables, or home sensors. Participation is opportunistic: devices appear when they’re idle, on Wi‑Fi, and charging. That gives you scale and coverage, but also extreme variability—spotty connectivity, small local datasets, and frequent dropouts—so training has to tolerate partial participation and noisy updates.
Cross-silo federated learning looks like hospitals, bank branches, or regional data centers. The number of participants is limited and known, links are more stable, and you can often run longer, more controlled training jobs. The trade-off shifts to governance and coordination: negotiating who can participate, how models are evaluated, and what happens when one site’s data distribution dominates. It can be operationally easier than cross-device, but it often costs more upfront in integration, security reviews, and ongoing cross-party change management.
Privacy and security: what FL gives, and what it doesn’t
A common misconception is that federated learning “solves privacy” because raw records stay put. It does reduce one obvious exposure: you’re no longer creating a central copy of everyone’s data just to train a model. That can help with data-minimization arguments and lowers the blast radius of a warehouse breach. But the messages you do send—gradients or weights—can still leak information about rare phrases, outlier patients, or unusual transactions if an attacker can probe or observe updates over time.
Most real deployments pair FL with additional controls, and each adds cost or complexity. Secure aggregation hides individual updates from the coordinator, but complicates debugging and can fail when too few clients finish a round. Differential privacy can bound what any one user contributes, but it often trades accuracy for privacy, especially on small or skewed local datasets. You also have to assume active threats: malicious clients can poison training, and curious servers can try to infer sensitive attributes. FL changes the risk profile; it doesn’t eliminate it.
The messy reality: devices drop, data differs, updates skew
In the wild, federated rounds rarely look like a clean average of “representative” clients. Phones go offline mid-round, hospital jobs get preempted by higher-priority workloads, and some participants simply can’t meet the compute or bandwidth budget often enough to matter. If you only train on devices that are idle, charging, and on Wi‑Fi, you’re also selecting for a particular kind of user behavior, which can quietly shift model performance away from the population you care about.
Even when participation is stable, the data usually isn’t. Local datasets are non-IID: one clinic sees a different patient mix, one branch sees different fraud patterns, one region types different slang. That makes updates disagree, and naive averaging can chase noise or overfit to whichever clients have more examples or higher update magnitude. Practical systems add weighting, clipping, client sampling rules, and stricter evaluation splits, but that introduces governance questions and tuning work. The basic promise holds, yet you still pay for messiness: more rounds, more monitoring, and more time explaining why “global” improvements can hide local regressions.
Operational patterns that make federated training workable
A workable federated pipeline starts by treating training as a scheduled service, not an ad-hoc job. Clients are admitted with clear eligibility rules (idle, power, bandwidth, minimum data), and each round samples a subset to control cost and limit bias from “always-on” participants. Updates are commonly clipped and normalized before aggregation to prevent a few clients from dominating, and servers keep per-client metrics so you can detect chronic outliers without seeing raw data.
Teams also separate “learn” from “ship.” A candidate global model is evaluated on held-out data at multiple sites or on-device test cohorts, and only promoted if it clears both overall and worst-case thresholds. Rollouts look like feature launches: staged deployment, canary clients, and rapid rollback when a region regresses. The secure aggregation and privacy accounting reduce observability, so debugging is slower and you often need more rounds, more instrumentation, and tighter change control than centralized training.
When federated learning is the right tool (and when it isn’t)
You’ll feel federated learning’s value when the data is high-signal but politically, legally, or operationally hard to centralize: text typed on phones, clinical notes behind hospital firewalls, transaction streams fenced by jurisdiction, or partner data that can’t be pooled. It also fits when personalization matters and you can tolerate slower iteration in exchange for broader coverage. The hidden requirement is operational maturity: versioning, monitoring, and a plan for attacks and drift.
It’s usually the wrong choice when you already have a clean path to centralized training, when you need fast experiments, or when debugging and reproducibility are top priorities. If the model is small and the data is easy to move, FL can add cost without adding much privacy. It also struggles when labels are sparse, devices are too weak, or your stakeholders won’t accept accuracy loss from differential privacy.