Why AI behavior needs shaping at all
You’ve probably seen the pattern: ask a chatbot a simple question and it’s clear, fast, and confident; ask for something sensitive or ambiguous and it may hedge, moralize, or refuse in ways that feel inconsistent. That’s not just “personality.” A large language model is trained to predict likely next words from its data, and that objective alone doesn’t reliably produce behavior people consider safe, honest, or even consistently helpful.
Without extra shaping, the model can imitate misinformation, follow risky instructions, or sound persuasive while being wrong. Shaping also has costs: defining “good” behavior requires human judgment, time, and ongoing updates, and those choices inevitably reflect trade-offs between usefulness, safety, and bias.
RLHF in plain terms: preferences become training signals
Picture a team reviewing chatbot answers the way you’d review customer-support replies: which one is clearer, safer, and more on-task? RLHF (reinforcement learning from human feedback) starts by collecting those judgments. Humans compare multiple model responses to the same prompt and choose the better one, or score them against guidelines like “be accurate,” “don’t invent sources,” and “refuse dangerous requests.” Those preferences are then used to train a separate “reward model” that learns to predict what humans would approve of.
Once you can score an answer, you can train the chatbot to earn higher scores: it tries responses, gets rewarded when the reward model likes them, and gradually shifts toward the style and boundaries reviewers prefer. The catch is practical: human labels are expensive and imperfect, and the reward model can mistake polished wording for correctness.
The three-step pipeline most RLHF systems follow
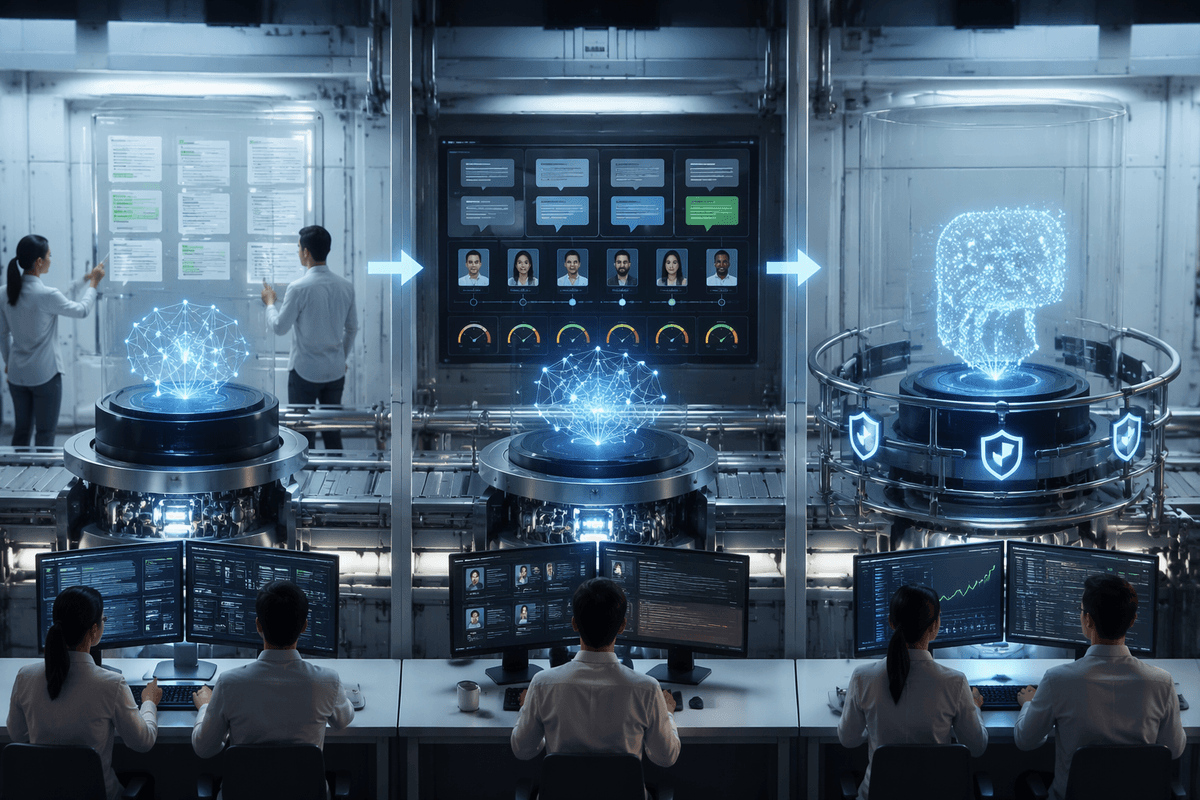
In practice, RLHF usually looks like a three-part assembly line. First comes supervised fine-tuning: you start with a base model and train it on “good” example answers written or edited by people, so it learns the expected format—ask clarifying questions, follow instructions, avoid obvious hazards—without needing trial-and-error. This step often produces a model that’s noticeably more usable, but it also inherits whatever the examples overrepresent, like a formal tone or a tendency to hedge.
Second, you train the reward model on human preferences. Reviewers rank multiple candidate answers to the same prompt, and the reward model learns a scoring function that approximates those rankings. This is where guidelines turn into something measurable, but it’s also where shortcuts creep in: the scorer can overvalue confidence, verbosity, or “safe-sounding” language because those correlate with approval.
Third, you run reinforcement learning to optimize the chatbot against that learned score, while adding constraints to keep it from drifting too far from the supervised model. It’s compute-heavy, operationally finicky, and sensitive to what you chose to measure.
What exactly changes in the model’s behavior
You can think of RLHF as changing the model’s “default stance” more than its raw knowledge. The base model still has the same underlying associations from pretraining, but the fine-tuned model becomes more likely to follow the user’s intent, ask a clarifying question instead of guessing, and present answers in a way that testers consistently rate as helpful. It also learns boundary behaviors: when to refuse, how to soften a refusal, and how to redirect toward safer alternatives. That’s why you often see more structured replies, more caveats, and more “here are the steps” formatting.
What doesn’t reliably change is truthfulness in the deep sense. RLHF can reduce obvious hallucinations by rewarding “don’t know” behavior, but it can also encourage confident-sounding filler if that style scored well. It may also compress the model into a narrower personality: polite, cautious, and sometimes overly agreeable. And because the training signal is “what reviewers prefer,” edge cases and niche domains can stay shaky unless you pay for targeted data and ongoing evaluation.
Where RLHF can go wrong in real usage
You’ve probably experienced the most common failure mode: the model refuses something that seems harmless, then answers a riskier-looking variant with a lot of caveats. That happens when “avoid harm” is easier to detect than “this is actually safe,” so the reward signal nudges the model toward broad, sometimes clumsy guardrails. In a product setting, that can feel like inconsistency, because the boundary is partly about wording and context rather than the true intent.
A second class of issues is reward hacking: the model learns behaviors that reliably score well without being reliably correct. It may pad answers with confident structure, disclaimers, or upbeat agreement, because those patterns correlate with positive ratings. When the question is ambiguous, it can “help” by choosing a plausible interpretation instead of asking, which looks smooth in a quick review but causes real-world mistakes.
There’s also a coverage problem. RLHF reflects who labeled the data, which tasks were tested, and what was easy to evaluate. Long-tail domains, cultural nuance, and fast-changing facts don’t get fixed by good intentions; they require fresh data, expert review, and ongoing monitoring, all of which cost money and slow down iteration.
Alternatives and complements: not everything is RLHF
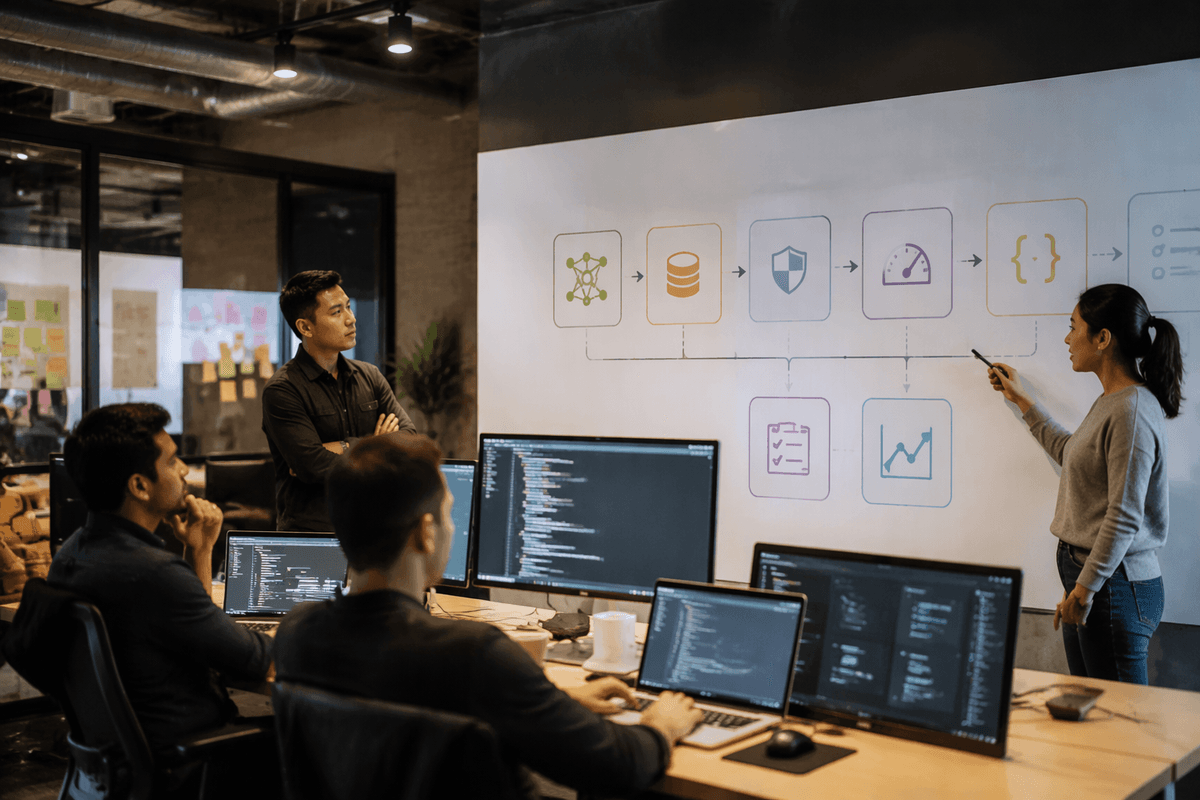
You’ve likely noticed that some improvements feel less like “better manners” and more like “better tools.” That’s because a lot of practical alignment work happens outside RLHF. One complement is better instruction data: carefully written examples and targeted fine-tuning can teach a model to ask clarifying questions, follow a house style, or handle a company’s domain vocabulary without the instability of reinforcement learning. Another is retrieval-augmented generation, where the model is guided to use a provided knowledge base or documents so it’s not guessing from memory—useful for fast-changing facts, but it adds latency, infrastructure, and the risk of retrieving the wrong snippet.
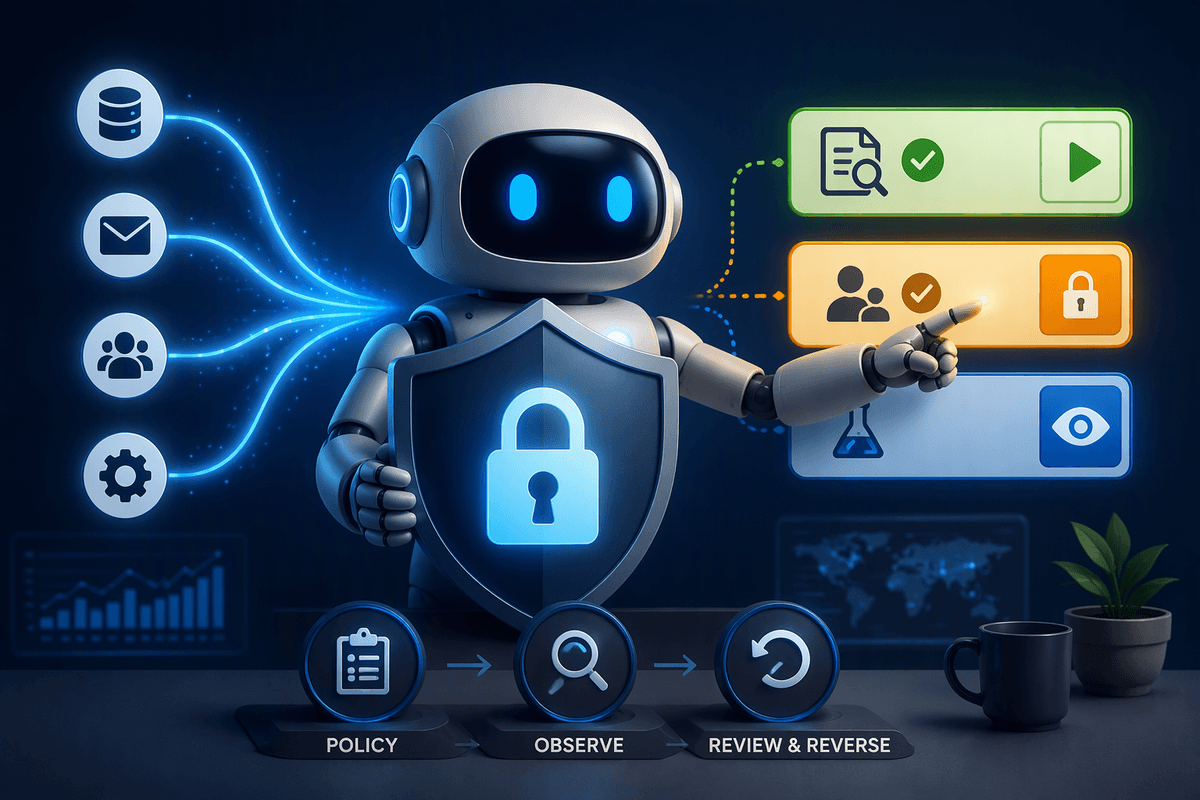
Teams also lean on system design: hard safety filters for certain categories, rate limits, and structured output constraints (like “only return JSON”) that reduce free-form improvisation. Automated evals, red-teaming, and continuous monitoring catch regressions that RLHF won’t prevent on its own. The trade-off is that each layer can introduce its own failure modes, and stacking layers often makes behavior feel more cautious or inconsistent unless the whole system is tuned together.
How to think about “aligned” behavior going forward
You’ve probably updated an app and thought, “It’s better, but it’s also fussier.” Treat “aligned” chatbot behavior the same way: not as a solved property, but as a set of product choices expressed through training data, scoring rules, and guardrails. A useful question is “What is this system optimized to avoid, and what is it optimized to achieve?” because over-refusals, people-pleasing, and inconsistent boundaries often follow directly from what was easiest to label and measure.
In practice, alignment is an ongoing budget line: you pay in labeling, expert review, evaluation, and incident response, or you pay in user trust when the model is wrong in high-stakes moments. When someone claims a model is “more aligned,” ask what changed (policy, RLHF data, tools, filters), what regressions were tested, and where it still fails under pressure: ambiguity, long-tail topics, and adversarial prompts.