Why distillation matters when models feel too big
You’ve probably shipped a feature that works great in a demo, then falls apart in production because the model is slow, expensive, or hard to run where you actually need it. A large model might hit your quality bar, but it can also blow up p95 latency, GPU budget, mobile battery, or on-prem constraints. That gap is where distillation matters: it’s a way to keep much of the behavior users like while moving to a smaller, cheaper model that’s easier to deploy and scale.
Unlike “just pick a smaller model,” distillation tries to transfer what the big model learned about the task, not only the training labels. The practical appeal is that you can often keep the same product surface area while cutting inference cost. The practical catch is that it’s not free: you pay in training complexity, teacher inference cost during distillation, and the risk that edge cases and safety behaviors don’t carry over unless you measure and tune for them.
Teacher vs. student: what gets transferred
Picture the teacher as the model you trust to answer well today, and the student as the one you can afford to run tomorrow. In distillation, the student isn’t trying to “memorize the dataset.” It’s trying to match the teacher’s behavior: not just which answer is correct, but which answers are plausible, how confident the model is, and what style or format it tends to use. That extra information shows up as probability distributions over tokens, ranked options, or intermediate representations, and it often carries more signal than a single hard label.
What transfers best are repeatable patterns: phrasing, domain conventions, and the teacher’s boundary around common cases. What transfers poorly are rare edge cases, subtle safety refusals, and long-horizon reasoning that depends on a very large internal workspace. If your teacher’s strength is “knowing what not to do,” assume you’ll need explicit evaluation and targeted data to preserve that in the student.
What kinds of distillation you can use
You see different distillation “flavors” depending on what signal you ask the student to imitate. The most common is output distillation: the student trains on the teacher’s token probabilities (often with a temperature to soften the distribution), which preserves preferences among plausible next words instead of just copying final text. A simpler variant is response distillation, where you store teacher-generated answers as training targets; it’s easier operationally, but it can bake in teacher quirks and hide uncertainty.
When outputs aren’t enough, you can distill deeper signals. Feature or representation distillation nudges the student’s internal activations toward the teacher’s, which can help on classification, retrieval, and structured prediction, but it increases engineering effort because layers rarely line up cleanly. There’s also preference distillation: train the student to rank the teacher’s better completions over worse ones, which often aligns style and helpfulness. The constraint across all types is cost: you pay to run the teacher at scale to generate the training signal, and that can dominate the project budget.
Choosing the student: size, architecture, and constraints
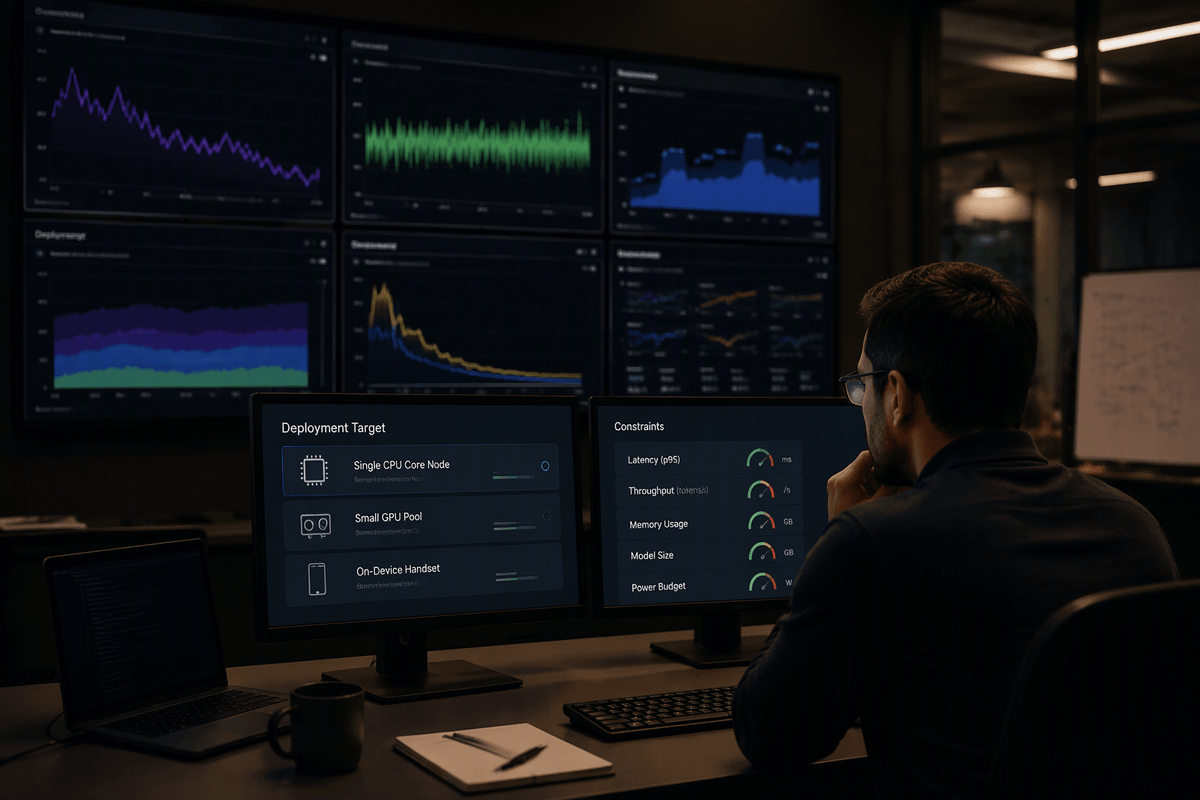
The most common mistake is picking a student by parameter count alone. Start with the constraint you actually feel in production: do you need sub-second p95 on a single CPU core, steady throughput on a small GPU pool, or something that can run offline on-device without draining battery? Those targets translate into a hard ceiling on memory footprint, context length, and tokens-per-second, which quickly narrows the field more than “small vs. big” ever will.
Architecture choices matter because distillation can’t magically give a tiny model the same “working room” as a large one. If long prompts and tool-heavy workflows are core to your product, you’ll usually prefer a student that keeps similar attention and context handling, even if you cut depth or width. If your workload is short, templated, and high volume, a simpler student can win on throughput and cost, and you can patch gaps with retrieval or routing.
Plan for practical friction: students that are fastest to serve are not always the easiest to fine-tune, and sometimes the cheapest path is a slightly larger student that hits quality with fewer distillation iterations and less teacher-generated data.
Training setup that makes distillation actually work
You’ll recognize a failing distillation run because the student looks good on a few canned prompts, then drifts in tone, format, or refusal behavior once users hit it with real inputs. The fix is usually not “more training,” but a tighter setup: build a prompt and decoding spec that the teacher follows consistently, log those exact settings, and make the student train against the same conventions you plan to serve. If the teacher sometimes uses tools, citations, or JSON, treat those as first-class outputs with strict formatting checks, not optional style.
Most teams get better results by mixing signals: keep a portion of ground-truth labels (or human-written answers) so the student doesn’t inherit teacher mistakes, and use teacher probabilities or rankings to transfer preferences among plausible outputs. Start broad with high-coverage, everyday traffic, then add targeted batches for the failures you care about: long-context prompts, safety boundaries, domain edge cases, and “do not comply” scenarios. Budget for the real cost driver: running the teacher enough times to generate clean, diverse training targets, plus the storage and filtering work to remove low-quality or inconsistent generations.
Quality, safety, and cost trade-offs to measure
You’ll feel the trade-offs most clearly when you stop asking “does it answer?” and start measuring how it fails. Track quality in slices that match production: short vs. long prompts, common intents vs. tail queries, and “needs exactness” tasks like extraction or code edits. Look beyond average scores. A distilled student can keep the mean but lose calibration, so it sounds confident on wrong answers, or it overfits to the teacher’s tone and becomes less flexible when requirements change.
Safety needs its own scorecard because it’s easy to regress silently. Measure refusal precision and recall (it should refuse when it must, and comply when it should), plus jailbreak resilience, sensitive data handling, and tool-use boundaries if the model can take actions. Expect to spend time curating adversarial and policy-edge examples; they’re rare in organic traffic, but they define your risk.
Cost is not just cheaper inference. Add teacher-generation spend, filtering and storage, extra evaluation runs, and the ongoing cost of re-distilling when policies or product behavior change.
When distillation is the right move (and when not)
You’ll know distillation is worth doing when you already have a teacher that behaves the way you want, but it’s too slow or expensive to serve everywhere you need it. It’s especially strong for high-volume, repeatable workflows: customer support macros, structured extraction, code transforms, or tool-call formatting where “good behavior” is stable and easy to test. It also fits teams that can afford a one-time training project to buy down long-term inference cost.
It’s a weak fit when requirements are moving fast, your teacher’s edge comes from long-horizon reasoning, or you can’t reliably evaluate safety and tail cases. If your bottleneck is memory bandwidth or hardware availability, quantization or better batching may beat distillation with less operational overhead. Distill when you can define success precisely; don’t distill to “get a cheaper model” without a measurement plan.