Why LLM answers go wrong in practice
You ask an LLM a straightforward question—summarize a meeting, explain a policy, draft a requirements doc—and it replies smoothly, with bullet points and confident tone. Then someone spots a made-up detail, a missing constraint, or a claim that was true two years ago but not now. Another day, the same prompt produces a different answer. The writing quality can mask the uncertainty underneath.
In practice, errors come from several places: gaps or bias in training data, “best guess” text generation that can invent plausible facts, unclear prompts that let the model choose its own interpretation, and context limits that cause it to ignore or forget key details. When tools are involved—search, databases, calculators—bad retrieval or misread sources can look like model intelligence. Fixing this often adds cost: extra steps, verification time, and human review.
Training data limits: gaps, bias, and noise
Questions about specialized internal processes, local regulations, or recent product releases can expose gaps in an AI model’s knowledge. When its training data contains little information about a particular field, the model may draw on similar patterns from broader topics and produce an answer that sounds credible but gets important details wrong. Even in well-documented areas, information may be outdated. Prices, standards, organizational changes, and security guidance can all change after the model’s training data was collected.
Bias creates a different problem. If certain perspectives dominate the training material while others are poorly represented, the model may make skewed assumptions about typical users, potential risks, or accepted practices. This matters particularly in areas such as HR, healthcare, education, and public policy. The underlying data may also contain duplicated pages, weak explanations, contradictory accounts, or material designed to persuade rather than inform. By drawing on these mixed sources, the model may produce fluent, confident answers that reflect inconsistencies in the training material rather than conclusions supported by clear, verifiable evidence.
Model behavior: next-token guesses and hallucinations
Even with perfect training data, the model is not “looking up” a fact the way a database does. It generates text one chunk at a time by choosing what token is most likely to follow the prior tokens. That works well for fluent writing, but it also means the model will happily complete patterns that sound like an answer even when it lacks solid grounding. If your question resembles common templates (“What are the steps to…,” “Cite the regulation that…,” “Summarize the study that…”), the model may produce a plausible-looking completion: names, dates, citations, or implementation details that fit the shape of the request but were never verified.
Hallucinations often appear when you push for specificity the model cannot support: exact numbers, quotes, obscure acronyms, or “the official policy” for an organization it cannot actually access. You may also see inconsistency because small wording changes shift which pattern it follows, or because it is trying to satisfy multiple constraints at once. A practical constraint is that the model usually will not flag its uncertainty unless you explicitly require it, and adding validation steps can slow workflows and cost more.
Prompt and context issues: ambiguity, overload, and leakage
You have seen this when a prompt feels “clear enough” to you, but the model still makes a choice you did not intend. “Draft a summary” can mean executive highlights, detailed minutes, or action items; “approve this approach” can mean check for feasibility, compliance, or tone. If you do not pin down audience, scope, and success criteria, the model will quietly fill in those blanks. It may also treat examples you include as requirements, or treat a single edge case as the main case because it was described most vividly.
Context length and attention are the other trap. Long threads, pasted documents, and multiple instructions compete, and the model may prioritize the most recent or most strongly worded text, not the most important. Details can be dropped, names can be confused, and earlier constraints can be overwritten by later ones. Leakage is the subtle version: content from prior messages, templates, or retrieved snippets can bleed into the answer in ways you did not ask for, which is especially risky when prompts contain confidential fragments or when “use only this text” is not enforced.
Retrieval and tool failures: bad sources in, bad answers out
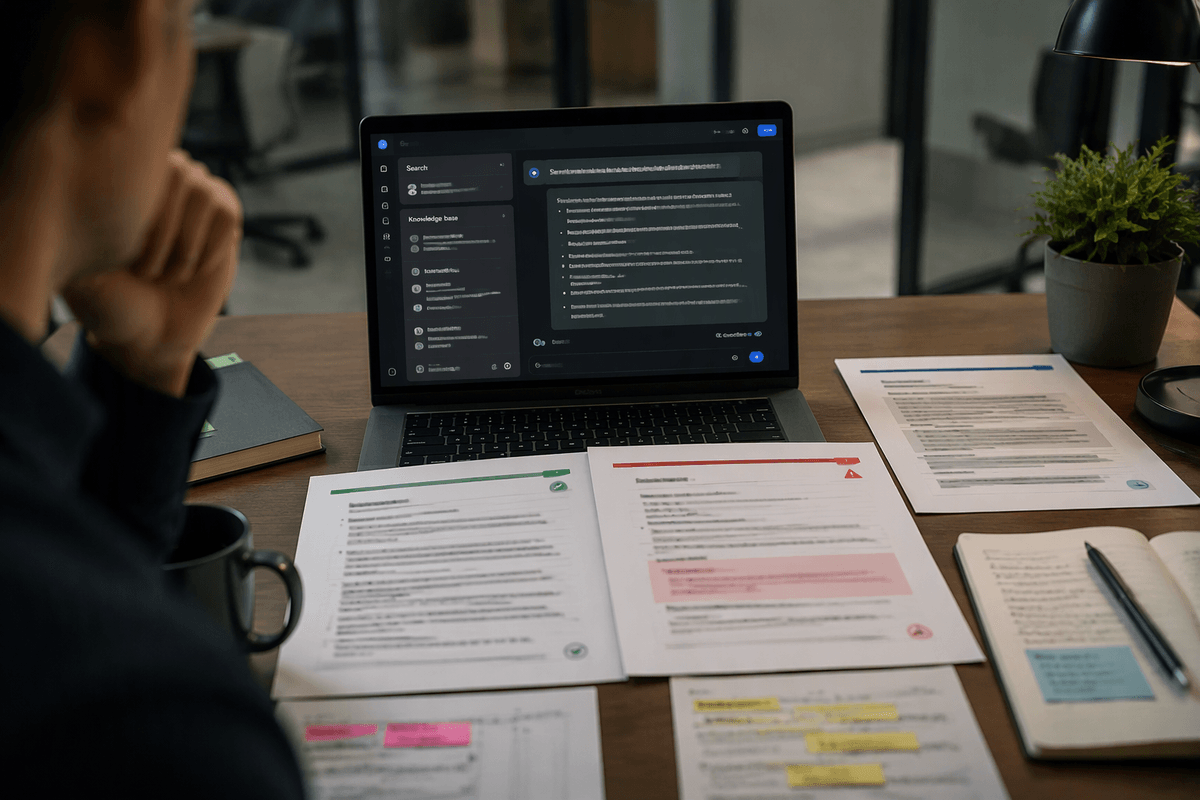
Connecting an LLM to search, a knowledge base, a ticketing system, or a spreadsheet can make its answers appear more reliable because they draw on external information. Retrieval, however, does not guarantee that the right evidence has been found. A search may return a document with a similar title, an outdated policy, or a popular page that lacks authority. Long excerpts create another risk: the model may rely on a confident statement while overlooking a qualification a few lines later. It may also combine details from several sources into a coherent explanation that none of them fully supports.
Errors can arise when the model works with the retrieved information, too. It may interpret “last 30 days” as “this quarter,” misread a table header, drop a negative sign, or treat missing values as zero. When tool activity is hidden, tracing the source of an incorrect answer becomes harder. The problem may lie in the search query, access permissions, an outdated index, or the model’s interpretation of the results. Reducing these failures requires better indexing, carefully maintained sources, detailed logs, and human review where accuracy matters. These measures take time and resources, but they help prevent a convincing yet incorrect answer from influencing an important decision.
Evaluation traps: what looks right but isn’t
A quick review may reveal clean formatting and a few accurate details while leaving serious reliability problems undetected. LLMs often reproduce the features associated with a strong answer: confident language, orderly reasoning, and familiar terminology. This makes surface-level evaluation unreliable. Readability, length, and the presence of citations do not establish that the content is correct. Citations may be fabricated, point to sources that do not support the claim, or accompany quotations whose wording has been subtly changed. Professional presentation is no substitute for verifiable evidence.
Testing also needs to go beyond straightforward questions. A model that performs well on general prompts may fail on the specific cases that matter most, including exceptions, thresholds, timelines, and precise definitions. Running several similar prompts does not necessarily solve the problem; the results may show consistent writing style rather than factual accuracy. Reliable evaluation requires more effort than generating answers. It needs verified reference answers, tests designed to expose likely errors, and reviewers who can check the evidence itself rather than simply judge whether a response sounds plausible.
Reducing risk: matching safeguards to error types
You have probably noticed that “be more accurate” is not an actionable requirement. The safer move is to match controls to the failure mode. For outdated or niche facts, require a source and a timestamp, or route the task through retrieval and treat anything uncited as a draft. For hallucination risk, force the model to separate “known from provided text” vs. “assumptions,” and reject invented quotes, numbers, or citations. For ambiguous prompts, add a short clarifying question step before drafting. For tool and retrieval errors, log queries, show snippets, and run simple cross-checks; this adds latency and review cost, but it makes mistakes traceable.