Why AI shifts the bar for online services
A customer who just got a crisp, conversational answer from an AI tool at work will feel the gap when your app replies with a slow form, a generic help article, or “we’ll get back to you in 48 hours.” That comparison happens even if your product hasn’t changed. AI didn’t only add a new feature category; it reset what “normal” responsiveness and clarity look like across the internet.
The bar shifts in predictable ways: speed becomes table stakes, explanations need to sound human while staying accurate, and self-serve flows must actually complete the task. The practical constraint is that improving these areas costs real money and risk budget: model usage fees, integration time, new failure modes, and higher expectations once you ship. AI raises the ceiling, but it also raises the minimum.
The new baseline: instant answers, any time
Think about the last time you checked a bank balance, changed a flight, or reset a password. You didn’t “open a ticket” in your head; you expected a clean answer in the same moment you hit friction. AI-trained expectations make that impulse stronger: customers now treat waiting as a product defect, not a service limitation. The baseline is closer to chat-speed clarification, with the system asking one or two tight questions and then doing the obvious next step.
That doesn’t mean every question deserves a live agent, or that every reply must be perfect on the first try. It means your experience needs a reliable fast path for the most common intents: account access, billing, plan changes, cancellations, delivery status, and policy edge cases. The hard part is coverage and confidence. Instant answers are only “better” if they’re correct, permissioned, and consistent with your actual rules. Getting there usually requires structured knowledge, logging, and 24/7 monitoring, not just a model switch.
Personalization without creepiness or mistakes
A familiar moment: a customer signs in, asks a question, and gets an answer that ignores what the system already knows—plan tier, region, device, last invoice, or the exact error they just hit. That kind of “generic helpfulness” now feels oddly outdated. But the opposite failure is worse: responses that sound like they’ve been watching too closely (“I noticed you usually log in at 7am from Chicago…”) or that confidently use the wrong account context. Personalization only helps when it’s clearly in-service of the task, and grounded in data the customer expects you to use.
The practical standard is “minimum necessary context.” Use first-party signals that reduce steps (show the right cancellation policy for their plan, prefill the relevant transaction, explain the error code they’re seeing) and be explicit about your sources when it matters (“Based on your last payment on Oct 12…”). Put guardrails around ambiguity: confirm identity before account-specific answers, ask a short clarifying question when confidence is low, and prefer safe defaults over clever guesses. This adds friction and engineering work, but it prevents the trust loss that one creepy or wrong answer can create.
Self-serve that actually resolves the issue
You can see the self-serve gap in the places customers most want “done,” not “informed”: refund a charge, change a shipping address, pause a subscription, recover an account, dispute a delivery, or remove a device. Too many help centers still stop at explanation, then hand the customer a form, a policy page, or a contact-us button. After using AI elsewhere, customers increasingly expect the self-serve layer to complete the workflow end-to-end: collect the few required details, show the consequences, and execute the change.
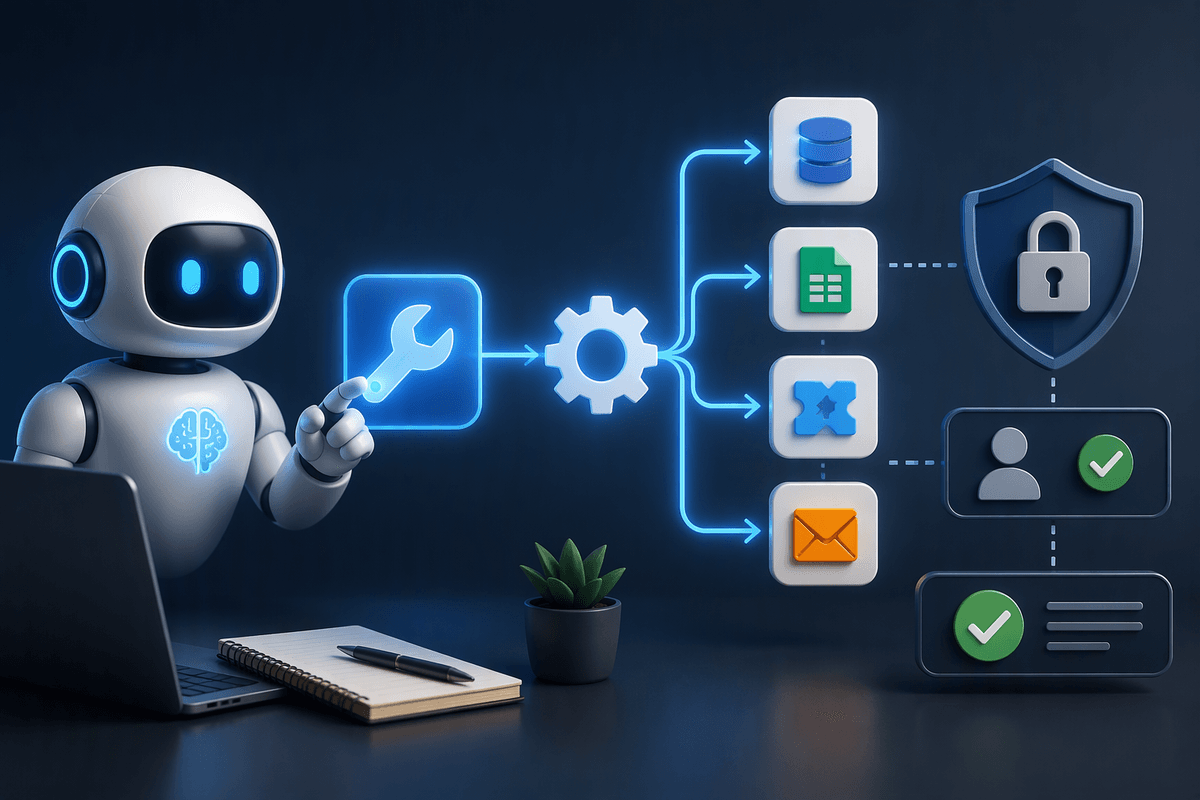
That’s less about chat and more about wiring. The system needs permissioning, audit logs, and clear boundaries on what it can and can’t do. It also needs graceful failure: when data is missing, an action is risky, or the user is outside policy, the experience should offer the next-best resolution (status, workaround, escalation) without restarting from scratch. The constraint is real: every “do it for me” flow touches payments, identity, and entitlement logic, so shipping faster often means investing in safer internal APIs first.
From “support” to proactive prevention
A familiar pattern shows up in dashboards: tickets spike after a broken release, a confusing price change, or an outage, and the support team becomes the cleanup crew. AI-driven expectations make that reactive posture feel even worse because customers assume the system can notice problems earlier and steer them away from failure. Proactive support isn’t a friendly pop-up; it’s the product reducing avoidable contact by predicting the next friction point and intervening before the user needs to ask.
In practice, that looks like “prevention loops” built from real signals: repeated failed logins trigger a guided recovery flow, an expiring card prompts a one-click update before the renewal fails, a delayed shipment proactively offers the right status and options, and a policy edge case is explained at the moment of decision. The hard constraint is correctness and restraint. Bad predictions create noise, and noisy alerts train customers to ignore you. The safest starting point is high-confidence triggers tied to measurable outcomes: fewer repeat contacts, fewer reversals, and faster time-to-resolution.
Consistency across channels and human handoffs
A customer rarely experiences your service in one place. They’ll start in an in-app chat, jump to email when they need attachments, check a help article on mobile, and sometimes reach for social when they’re frustrated. The expectation shift is that the story stays coherent: same policy language, same status, same next steps. AI makes inconsistency more visible because it can produce fluent but slightly different answers across channels, which customers interpret as “they’re making it up” even when each reply is individually reasonable.
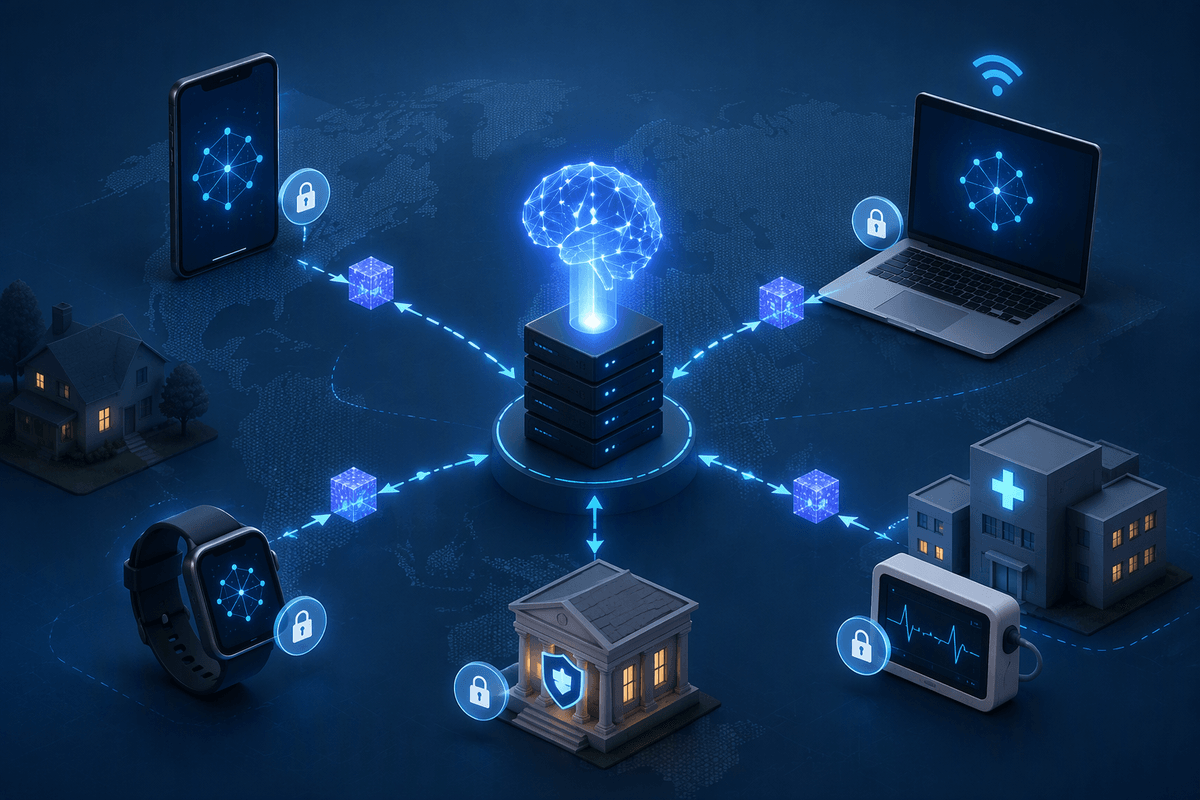
The practical move is to design “one brain, many surfaces.” Centralize the facts that must not drift (order state, eligibility rules, refunds, identity requirements) and force every channel to pull from that shared source, not a copy. Then make handoffs explicit. When a bot escalates, it should pass a short, structured packet: verified identity level, intent, key events, what was tried, and the customer’s chosen outcome. This takes work—shared tooling, taxonomy, data access controls—and it can slow experimentation, but it prevents the expensive loop of customers repeating themselves and agents undoing automated actions.
How to respond without chasing every AI trend
You’ll feel pressure to “add AI” everywhere, but the safer approach is to treat AI as an interface upgrade to specific jobs customers already try to complete. Pick two or three high-volume intents where speed and clarity matter, then define what “good” looks like in measurable terms: resolution rate, time-to-resolution, repeat contact, refund reversals, and escalation quality. Ship narrow, instrumented improvements before broad assistants.
Keep one operating rule: don’t automate what you can’t audit. Budget for evaluation, red-teaming, and ongoing content maintenance, not just model calls. When a capability increases risk (identity, payments, policy exceptions), gate it behind verification and clear fallbacks, even if that costs a few extra seconds.